Run inference on just the area you are zoomed into
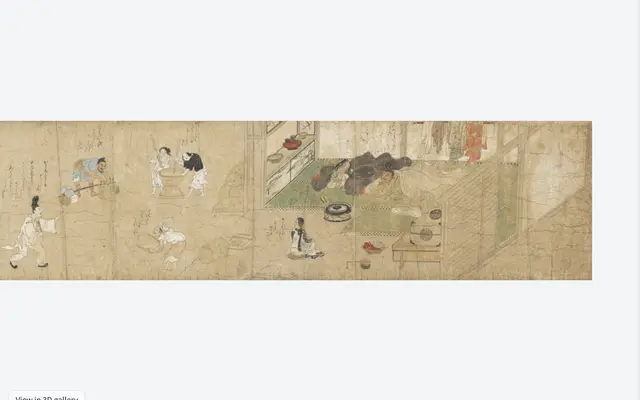
The Inference tab has a new button, “Run on the visible area”. Reading a long image such as a handscroll as a whole shrinks it so much that text and faces are lost; now only the area you are zoomed into is cut out and read. Move to another area and press it again to add to the results. With face detection on the Tale of Fukutomi, the whole image gave no faces, while two zoomed-in areas gave 14.
Try it in Kasane